•
Apache Spark·
Python
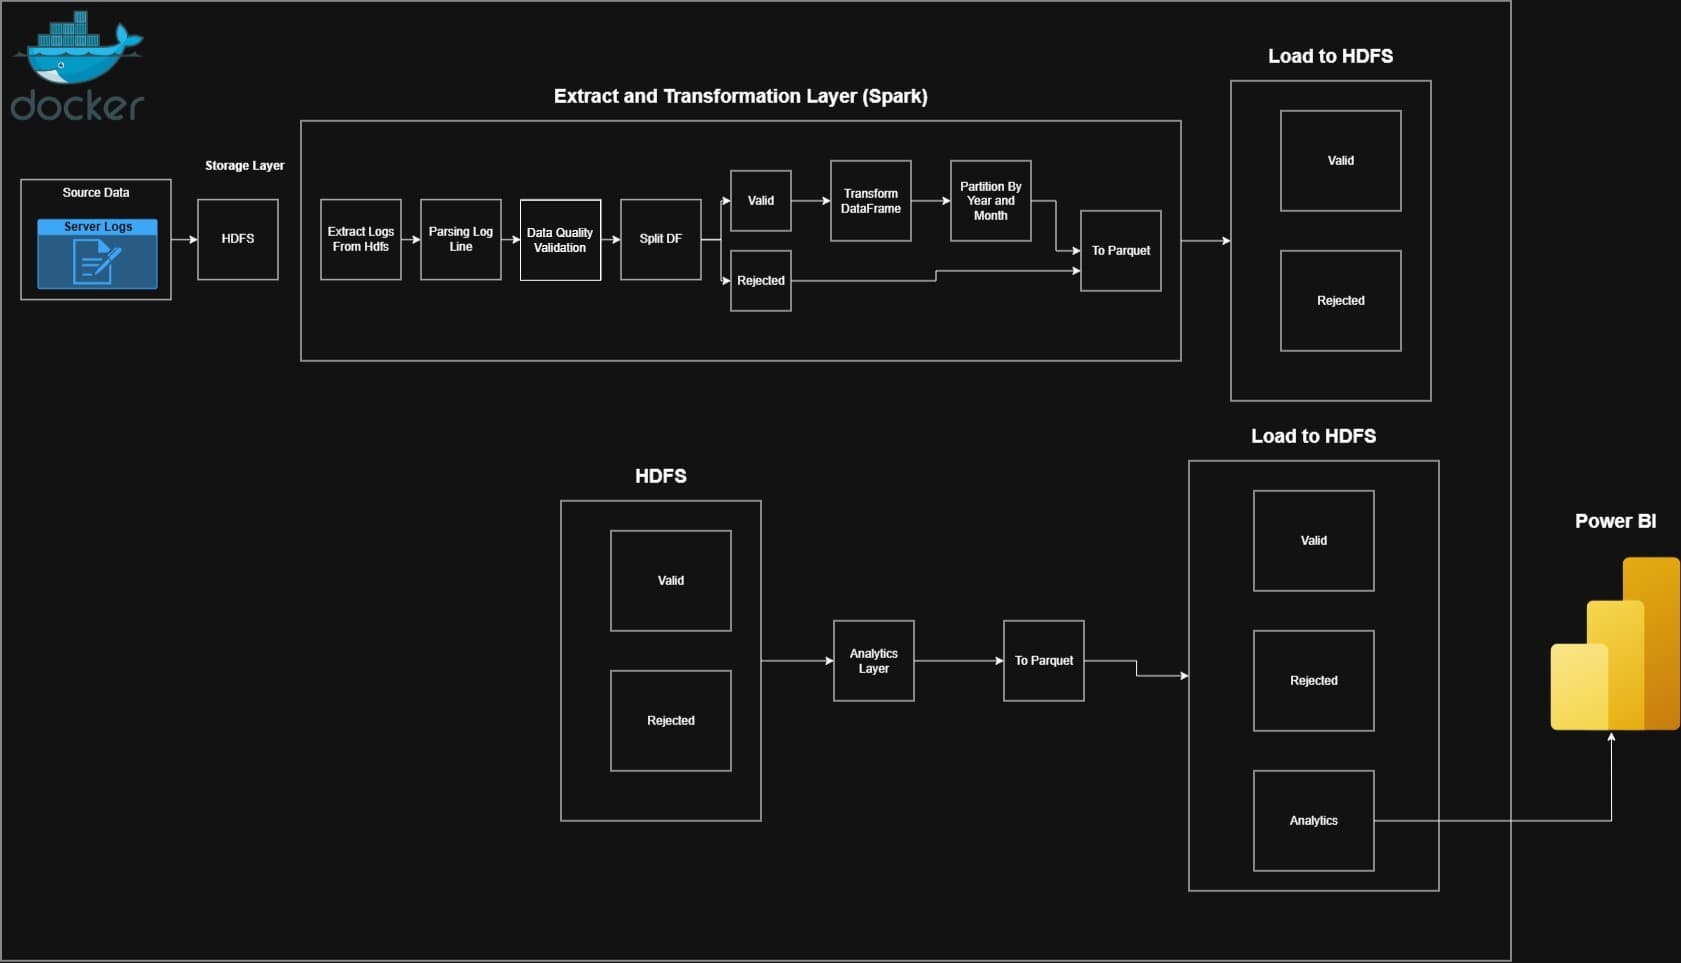
This project demonstrates an end-to-end Data Engineering Pipeline for processing approximately 3.3 GB of Nginx access logs using Hadoop HDFS and Apache Spark. The pipeline ingests raw log data into HD...
About this project
This project demonstrates an end-to-end Data Engineering Pipeline for processing approximately 3.3 GB of Nginx access logs using Hadoop HDFS and Apache Spark. The pipeline ingests raw log data into HDFS, parses and validates the records, separates invalid records into a dedicated rejection layer, transforms valid data into a structured schema, and stores the processed data as Parquet files partitioned by year and month. An analytics layer is then built on top of the processed data to generate request volume, HTTP status, endpoint, and data quality metrics. Finally, the analytics outputs are connected directly to an interactive Power BI dashboard through WebHDFS. The project also focuses on running a large-scale batch workload in a resource-constrained local environment using Docker, including Spark resource tuning and HDFS integration.
Stack:
Apache Spark